672 个模型在线

图像与视频,
凭空而来。 AI 图片、视频、音频与 3D 生成

图片 · Google

Nano Banana 2.1 Text-to-Image

Google's Nano Banana 2.1 is the latest Nano Banana text-to-image model, with gains in visual design, subject consistency and prompt adherence, 1K to 4K output and optional web search grounding.

试用模型 →€0.08起 每张图像
€0.01起
672图片、视频、3D、音频与文本模型
€3最低充值,一份余额通用所有模型
0订阅。生成失败不收费

顶尖模型,一个余额

文本生成图像、图像生成视频、图像生成 3D、文字转语音等,来自领先实验室,按结果计价。

图片

Nano Banana 2.1 Text-to-Image

Google

Google's Nano Banana 2.1 is the latest Nano Banana text-to-image model, with gains in visual design, subject consistency and prompt adherence, 1K to 4K output and optional web search grounding.

低至€0.08每张图像试用模型 →
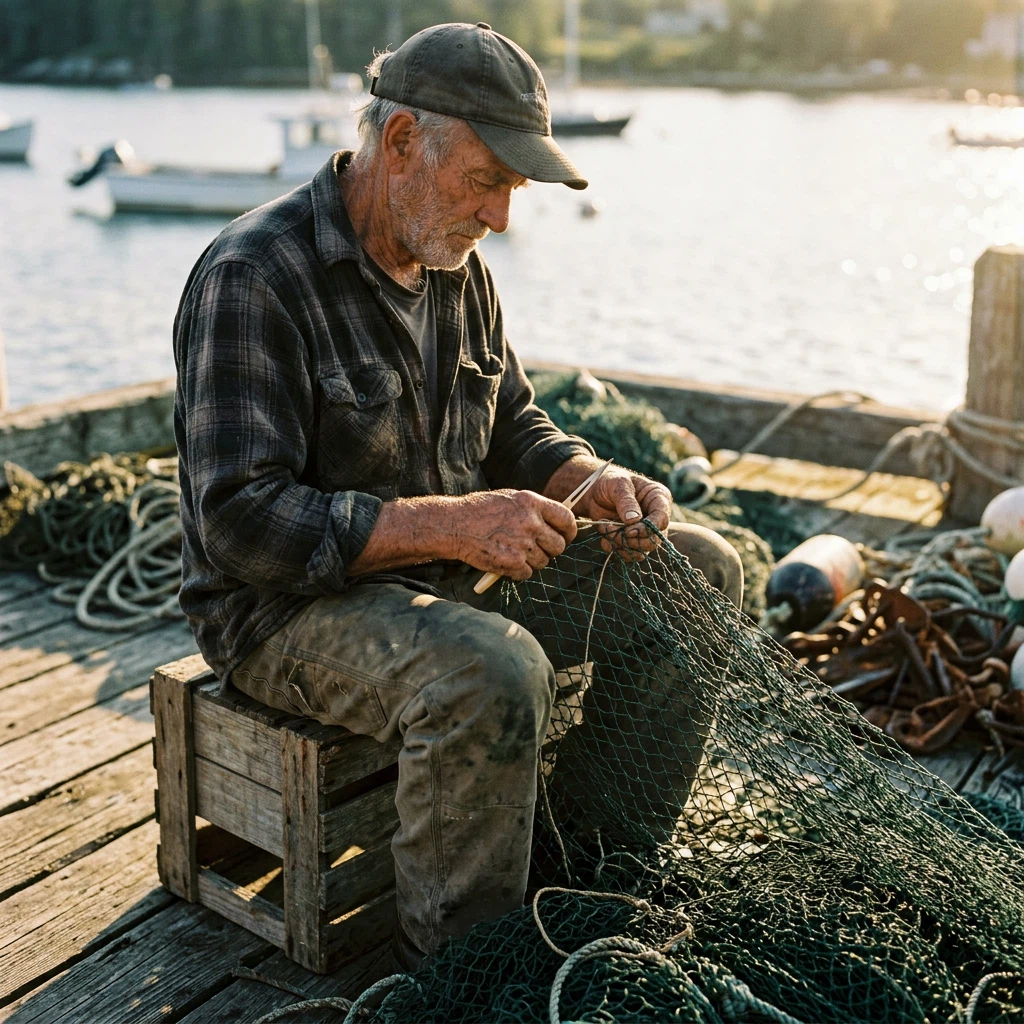
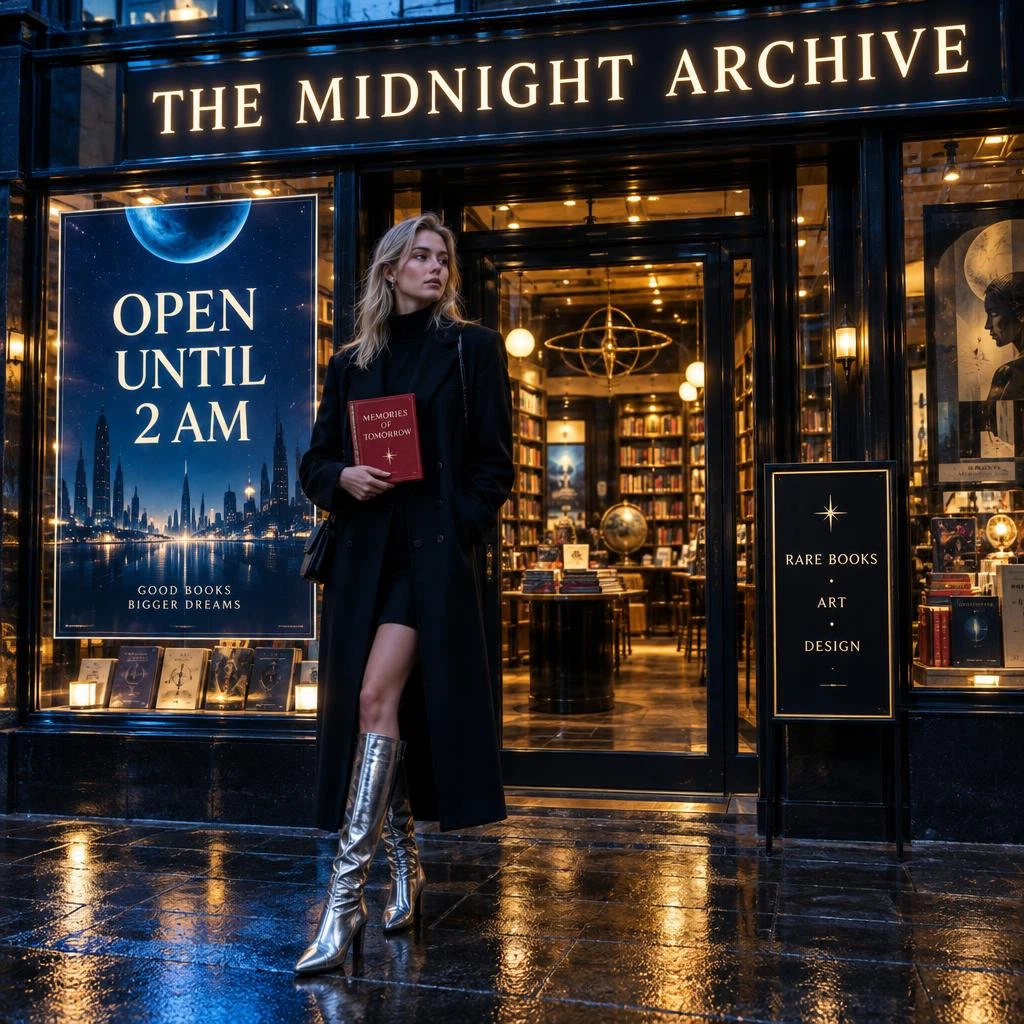
示例渲染:Nano Banana 2.1 Text-to-Image
图片

GPT Image 2.5 Flare Text-to-Image

OpenAI

OpenAI's GPT Image 2.5 Flare Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Flare is the fast, balanced GPT Image 2.5 tier for everyday generation at low latency.

低至€0.05每张图像试用模型 →
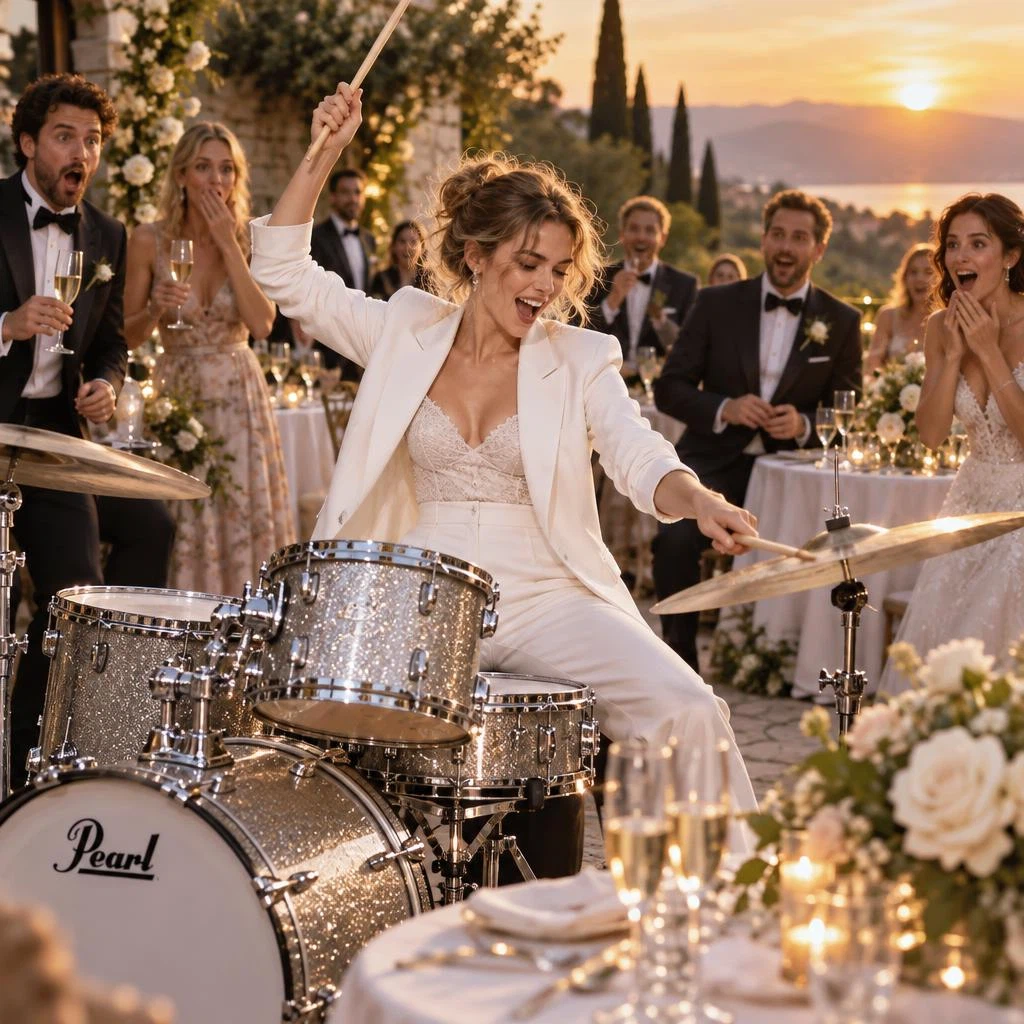
示例渲染:GPT Image 2.5 Flare Text-to-Image
图片

GPT Image 2.5 Sunburst Text-to-Image

OpenAI

OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail.

低至€0.05每张图像试用模型 →
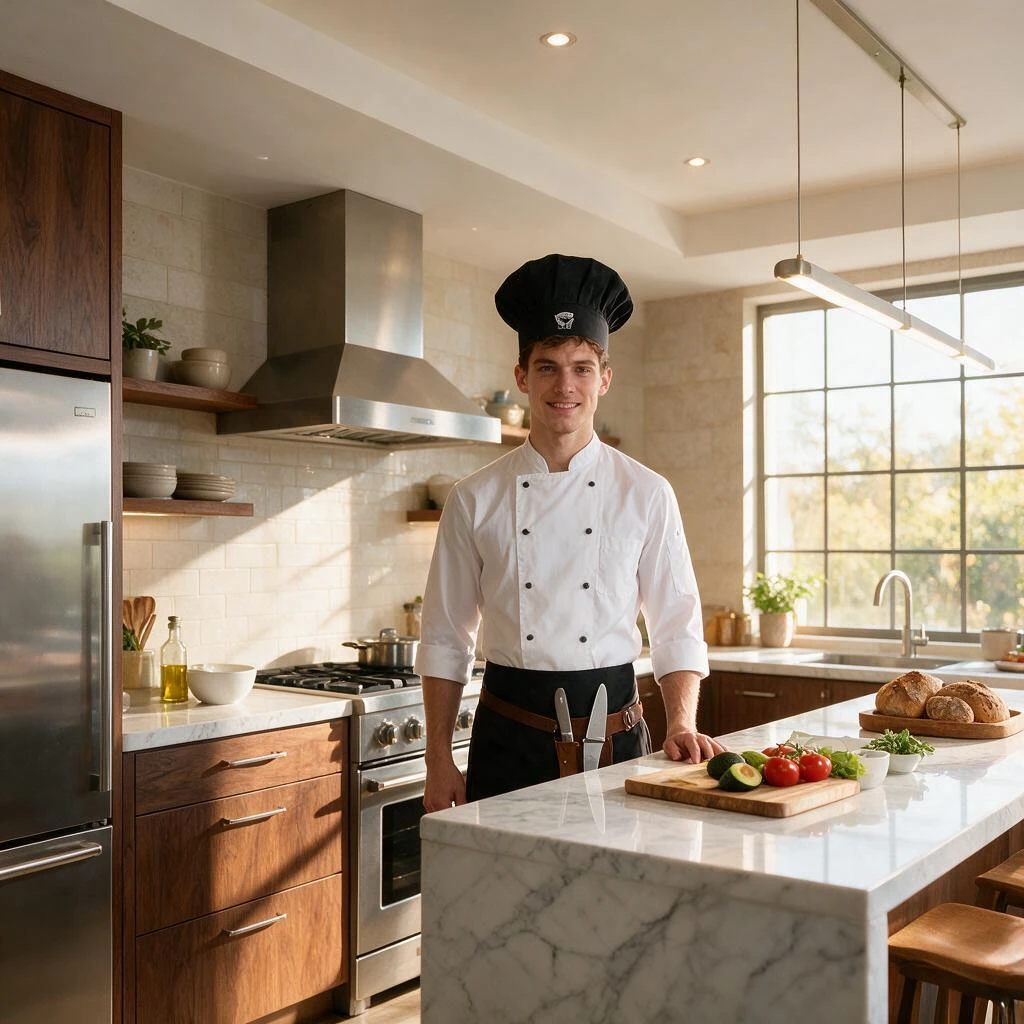
示例渲染:GPT Image 2.5 Sunburst Text-to-Image
视频

Seedance 2.5 Talking Avatar

Bytedance

Animate a portrait image from an audio recording with Seedance 2.5. Generate talking-avatar videos in 480p or 720p, processing up to the first 120 seconds of audio.

低至€2.20每个片段试用模型 →
视频

Wan 3.0 Prime Reference-to-Video

Alibaba

Alibaba WAN 3.0 Prime Reference-to-Video combines reference images, videos, and audio with prompts to create coherent videos with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.

低至€1.50每个片段试用模型 →
视频

Wan 3.0 Image-to-Video

Alibaba

Alibaba WAN 3.0 Image-to-Video converts a first-frame image into a video with optional last-frame guidance, flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.

低至€1.00每个片段试用模型 →
图片

Seedream V5.0 Pro Edit

Bytedance

Seedream 5.0 Pro API Preview Edit is ByteDance's advanced image editing model for single-image and multi-reference image generation.

低至€0.09每张图像试用模型 →
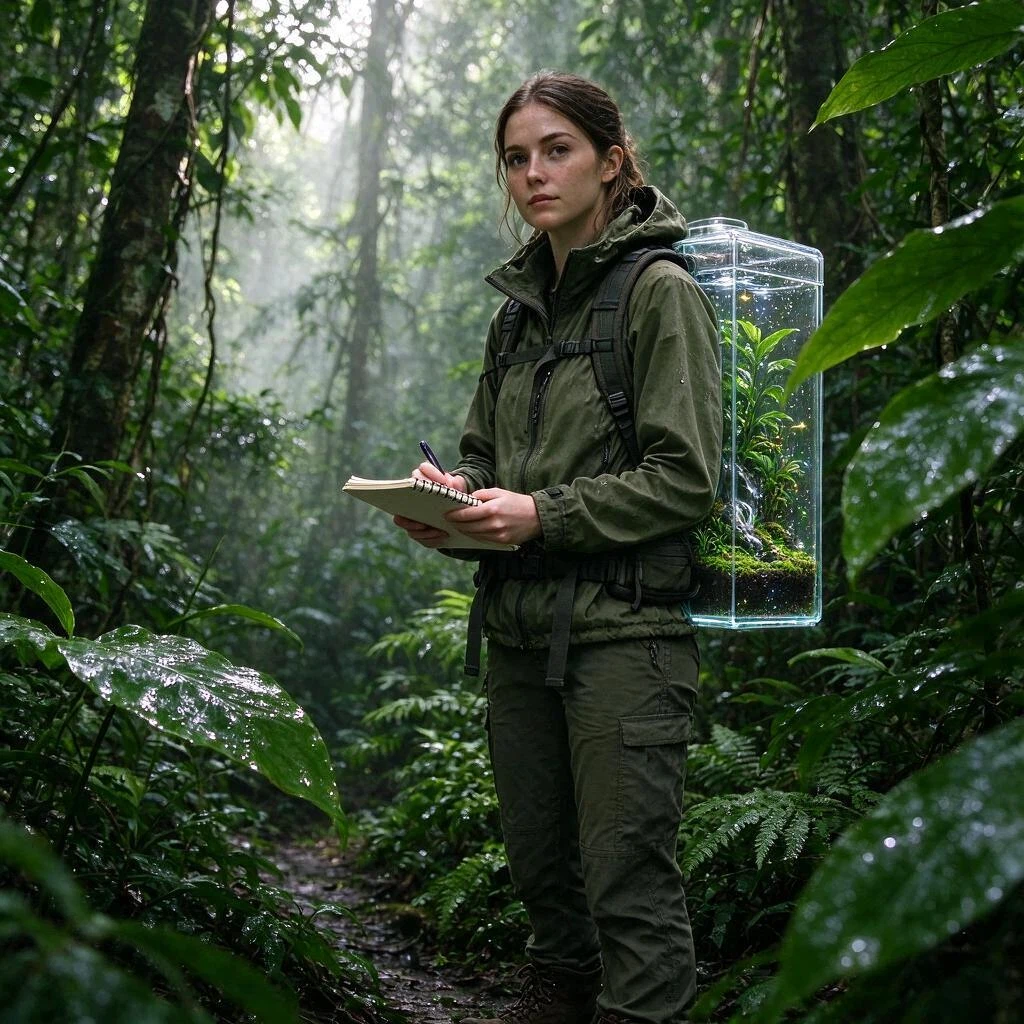
示例渲染:Seedream V5.0 Pro Edit
图片

Seedream V5.0 Flash Edit

Bytedance

Seedream 5.0 Flash Edit is ByteDance's fast, lower-cost image editing model for single-image and multi-reference image generation.

低至€0.06每张图像试用模型 →
示例渲染:Seedream V5.0 Flash Edit
图片

Qwen Image 3.0 Text-to-Image

Alibaba

Qwen Image 3.0 text-to-image model with high-quality image generation and advanced prompt understanding.

低至€0.06每张图像试用模型 →
示例渲染:Qwen Image 3.0 Text-to-Image
图片

Qwen Image 3.0 Pro Text-to-Image

Alibaba

Qwen Image 3.0 Pro text-to-image model with professional-grade quality and advanced prompt understanding.

低至€0.08每张图像试用模型 →
示例渲染:Qwen Image 3.0 Pro Text-to-Image
视频

Grok Imagine Video V1.5 Text-to-Video

xAI

Generate a short video from a text prompt with xAI Grok Imagine Video v1.5.

低至€0.16每个片段试用模型 →
图片

Grok Imagine Image V2.0 Edit

xAI

Grok Imagine Image V2.0 Edit transforms up to three input images according to a text prompt with configurable resolution and quality.

低至€0.16每张图像试用模型 →
示例渲染:Grok Imagine Image V2.0 Edit
查看全部672个模型 →

三步
得到成品画面

没有节点,也没有复杂的设置。描述需求,选择模型,留下你喜欢的结果。

  1. 01

    描述

    用简单的语言描述画面。模型支持时可以添加参考图。

  2. 02

    选择模型

    在图像、视频、3D 和音频模型之间切换,提示词保持不变。

  3. 03

    留下满意的

    比较结果,用另一个模型再次运行提示词,下载你喜欢的那一个。

开发者

专为
开发者打造

一个 API 调用所有模型,与网页应用共用余额。在设置中创建密钥;CLI 即将推出。

文档
1import { writeFile } from "node:fs/promises";2 3const API = "https://airogenia.com/api/v1/api/catalog";4const auth = { Authorization: `Bearer ${process.env.AIROGENIA_API_KEY}` };5 6// 1. Generate an image7const res = await fetch(`${API}/generations`, {8  method: "POST",9  headers: { ...auth, "Content-Type": "application/json", "Idempotency-Key": crypto.randomUUID() },10  body: JSON.stringify({11    modelId: "luma/uni-v1/text-to-image",12    inputs: { prompt: "Neon city street after rain, cinematic night", size: "16:9" },13  }),14});15let { generation } = await res.json();16 17// 2. Wait for the result18while (generation.status === "queued" || generation.status === "generating") {19  await new Promise((r) => setTimeout(r, 3000));20  ({ generation } = await (await fetch(`${API}/generations/${generation.id}`, { headers: auth })).json());21}22 23// 3. Save the file24const file = await fetch(`${API}/generations/${generation.id}/content`, { headers: auth });25await writeFile("result.jpeg", Buffer.from(await file.arrayBuffer()));
01 · 金额最低 €3
02 · 你将获得预估
€3余额
Still · 图片≈ 7Motion Turbo · 5 秒 720p≈ 0Motion · 5 秒 480p≈ 0
充值 €3 →

三种工作方式

先用快速图像模型起草情绪板,再用更清晰的模型完成主视觉,一个余额、一个标签页搞定。

艺术指导情绪板和关键帧

没有会被遗忘的订阅。接到客户项目时从 €3 起充值,每次渲染前都能看到准确价格。

自由职业按渲染付费

生成之前
先看这里

全部问题 →
如何计费?

你为欧元余额充值,最低 €3,每次生成都从余额中扣款。点击生成前,编辑器会显示确切价格;生成失败不扣费。

需要订阅吗?

不需要。没有月费,也没有需要取消的套餐。余额会一直保留在账户里,直到你用完。

怎么付款?

可使用 PayPal(同样支持银行卡),或在结账页显示的网络上使用加密货币(USDC 或 USDT)。付款确认后,余额立即到账。

生成的内容可以使用吗?

可以。我们不主张你所生成内容的所有权,也不限制商业用途。生成结果是否受版权保护,取决于你所在地的法律,详见许可页面。

输出内容由谁负责?

图片和短片由 AI 模型自动生成。Airogenia 不控制也不审核模型生成的内容,并不对其负责;如何使用结果,以及该使用在你所在地是否合法,由你自行决定。

能把图片变成短片吗?

可以。信息流或资源库中的任意图片都有“动画化”操作,会把它作为视频的首帧。

还有疑问?

给我们写信,会有真人回复。

邮件联系支持[email protected]价格所有模型及其价格